How it works
A model published in 1998 was rebuilt from its description, then the same search was run again on twenty eight years of additional data and a descriptor pool that did not exist at the time. This page is the whole account, including the parts that did not reproduce.
1. The 1998 model
Wessel, Jurs, Tolan and Muskal fitted percent human intestinal absorption to 86 compounds. The structures were encoded with 728 descriptors, reduced to 127 after correlated and near-constant columns were dropped. A genetic algorithm searched that pool and chose six descriptors, which were fed to a 6-4-1 feed forward neural network: six inputs, four hidden units, one output. The reported errors were 9.40 percent absorption units on the training compounds and 16.00 on an external set of 10 compounds.
The six chosen descriptors were dominated by hydrogen bonding and molecular geometry: how much of the surface could donate or accept a hydrogen bond, and how that surface was arranged. The model was small because the data was small, and the paper said so.
2. The reproduction
The descriptor software of 1998 is gone. ADAPT computed the 728 descriptors on hardware and in a language that no longer runs, and no archived build produces the same numbers today. Reproducing the model therefore meant reimplementing the six published descriptors from their written definitions rather than recovering their original code, and accepting that a reimplementation from a definition is not the same object as the original implementation.
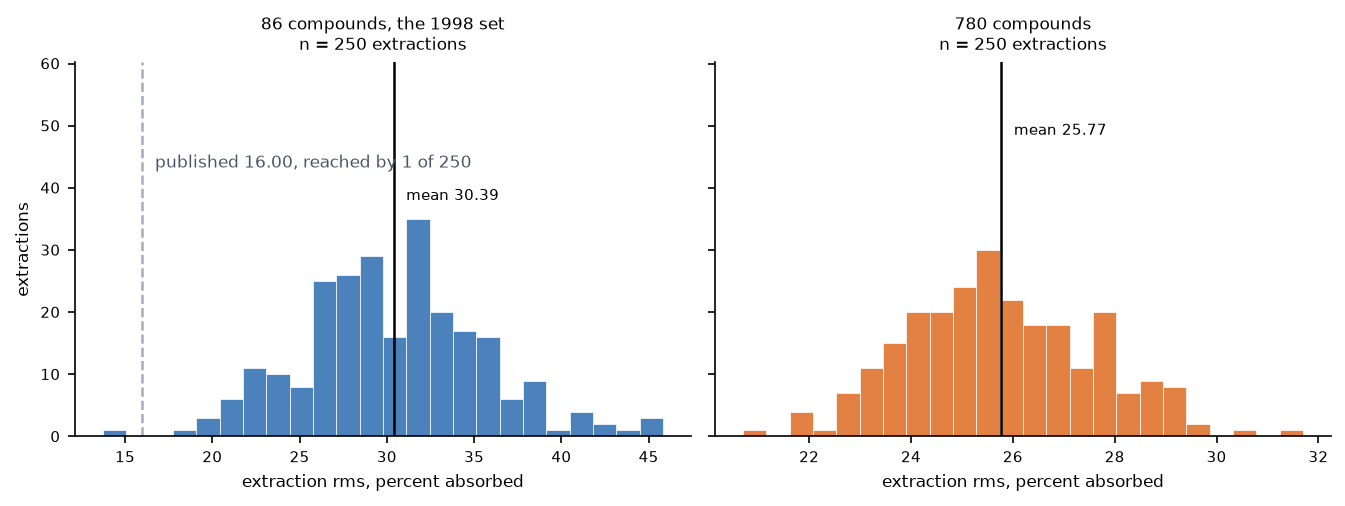
With the six descriptors reimplemented and a 6-4-1 network fitted to the same 86 compounds, the reproduction was measured the way the rest of this work is measured: over 250 stratified extractions rather than one split. It gives 13.43 percent absorption units on the training compounds, 29.37 in cross validation and 30.39 on the extracted compounds, against the published 9.40, 19.70 and 16.00.
The reproduction is therefore worse than the 1998 report. A single favorable split can land near the published figure, and one of these extractions does, but the distribution sits well above it. The method carries over; the published error belongs to the tail of what repeated extraction shows rather than to its middle.
3. How the models are built
Every endpoint is built the same way, and the shape of it is what makes the numbers mean anything.
The pool. Each model starts from a large set of calculated molecular descriptors, 1,301 for absorption and the Caco-2 small molecules, and 1,257 for the peptides. Inside every extraction that pool is cut by two objective rules: drop any descriptor whose values are more than 80 percent identical, then drop one of any pair correlating above 0.90. Between 127 and 184 survive, depending on the endpoint: about 148 for absorption, 181 for the Caco-2 small molecules, 142 for the Caco-2 peptides and 131 for the artificial-membrane peptides.
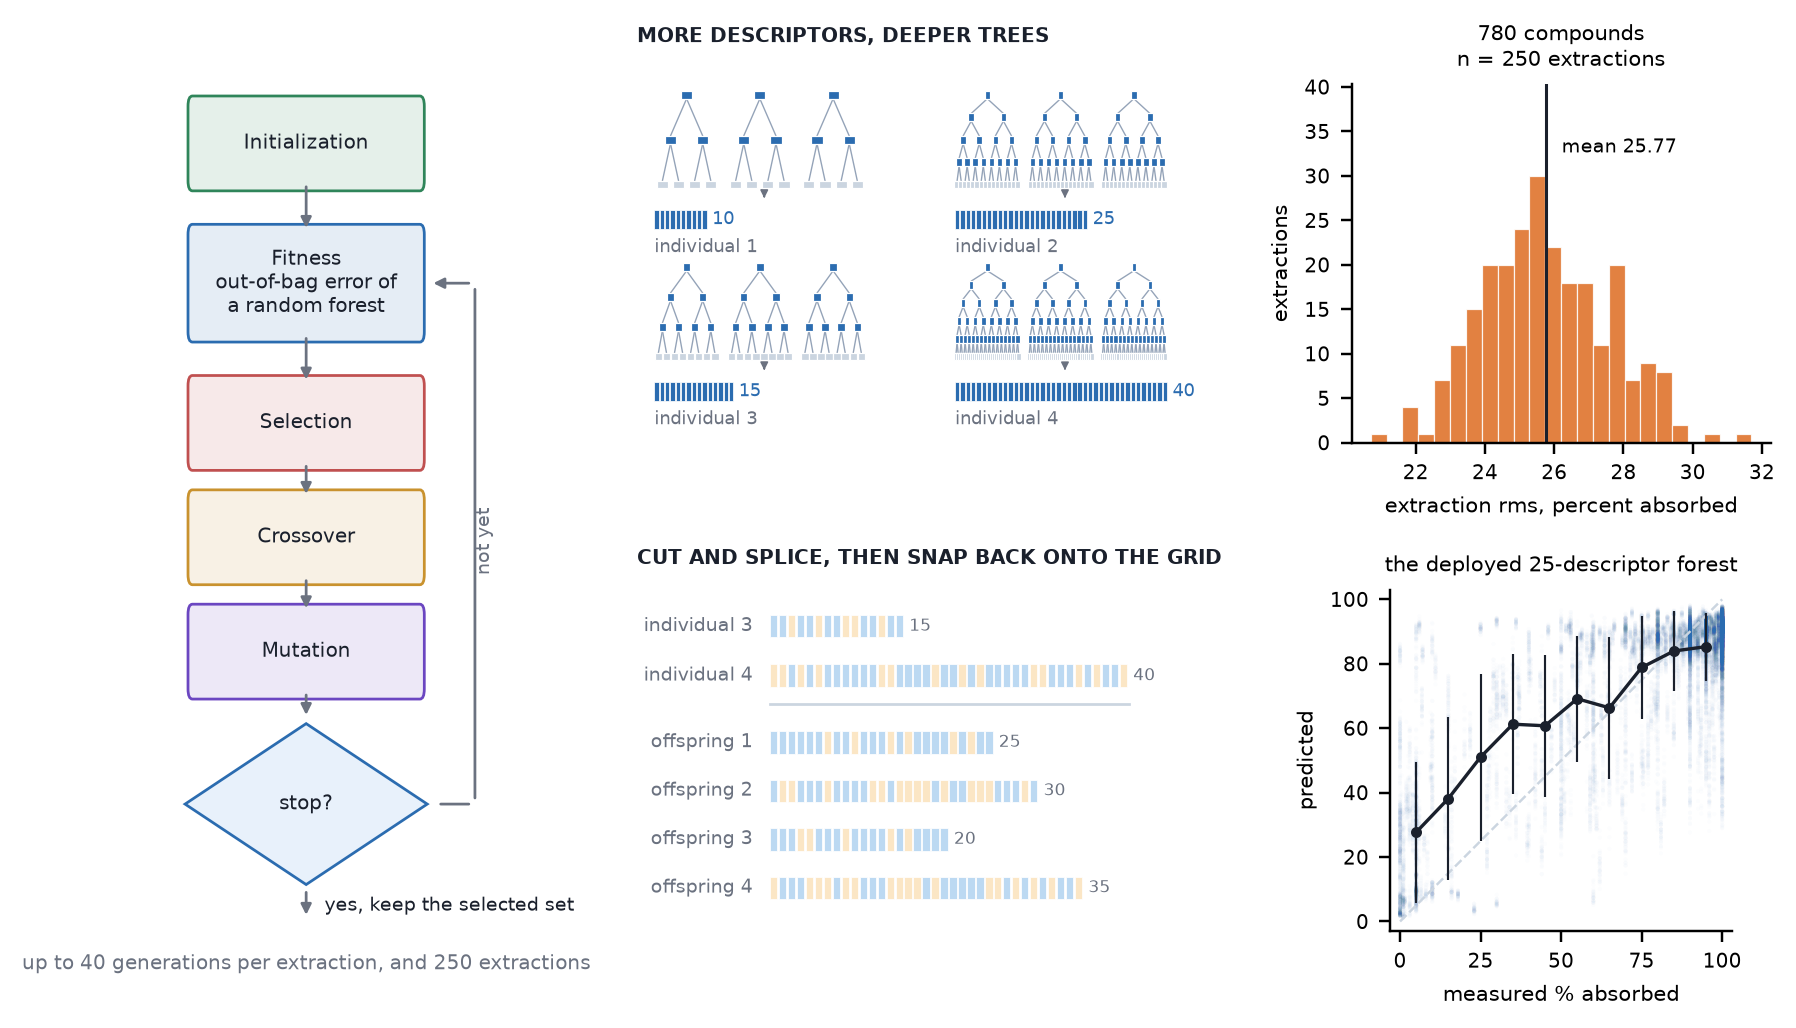
The search. A genetic algorithm evolves descriptor sets of 5 to 40 members in steps of 5, 5 to 55 for the Caco-2 small molecules and 5 to 60 for the Caco-2 peptides, for up to 40 generations with a population of 60. Absorption and the artificial-membrane peptides settle at a median of 25 descriptors, the Caco-2 small molecules at 55 and the Caco-2 peptides at 50. Each candidate is scored by a random forest out of bag, so the search never reads a compound outside its training group and the extracted group stays untouched until the search has ended.
The repetition. All of it runs again on 250 independent stratified extractions. That gives a distribution of set sizes, a recurrence count for every descriptor, and a distribution of errors rather than a single number that happened once.
The set that ships. The 250 selected sets are not identical, and they are not expected to be: the descriptor space is redundant, so many different sets do a similar job. What ships is the consensus, the most recurrent descriptors taken to the median selected set size. That union is not any one of the selected sets, so it has no error yet. It is fixed and evaluated over the same 250 extractions, and those numbers are the ones reported on this site.
The model that ships. One random forest, 300 trees, at least 2 samples per leaf, fitted on every compound in the dataset. Nothing is withheld, because the evaluation above is what states the performance, not a leftover test set.
3b. What the absorption search chose
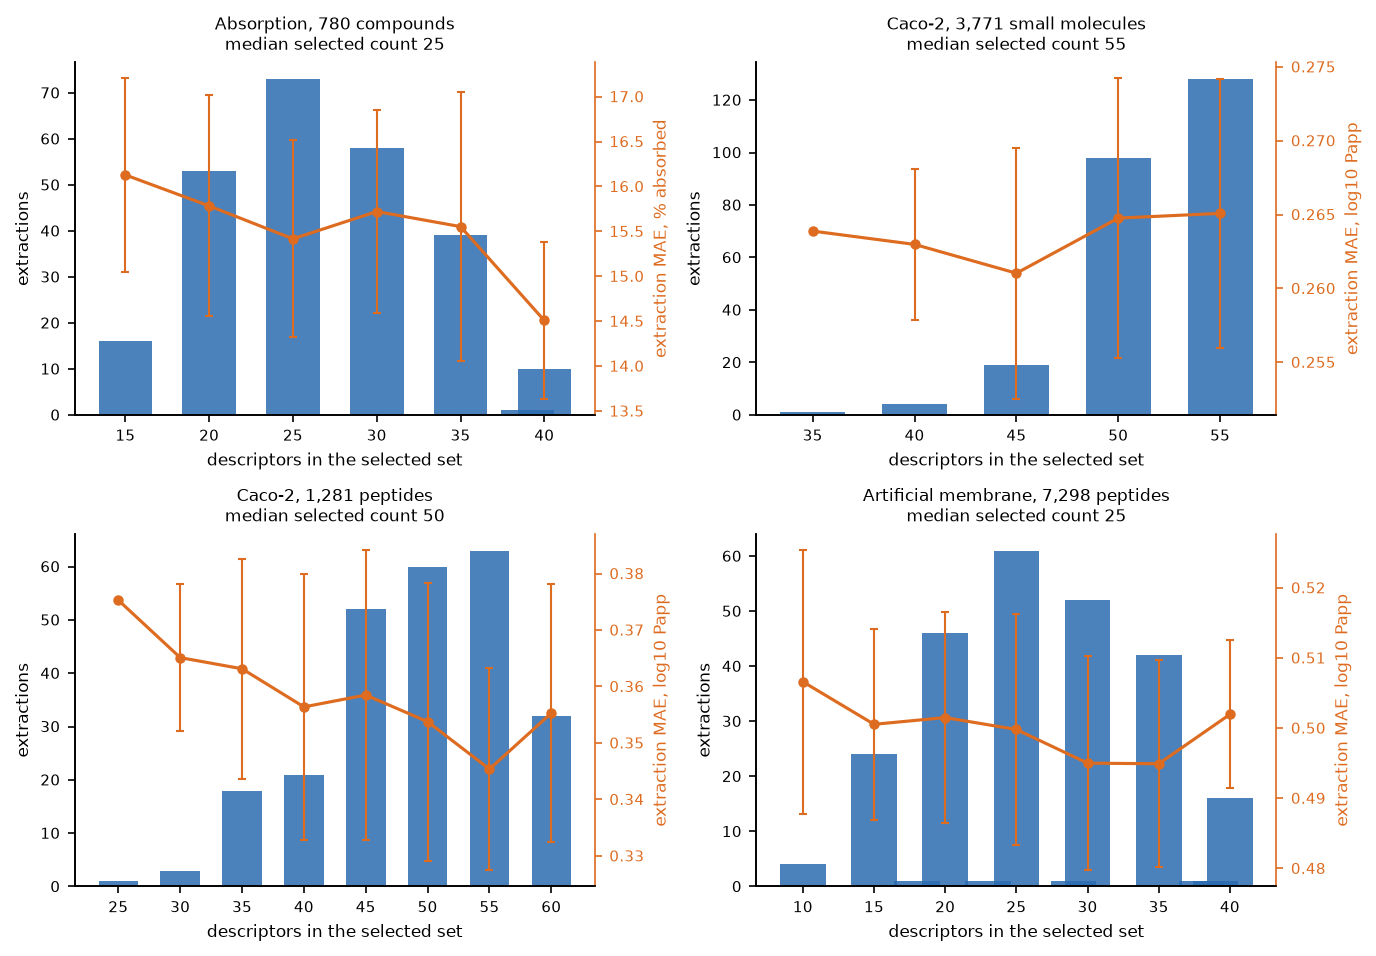
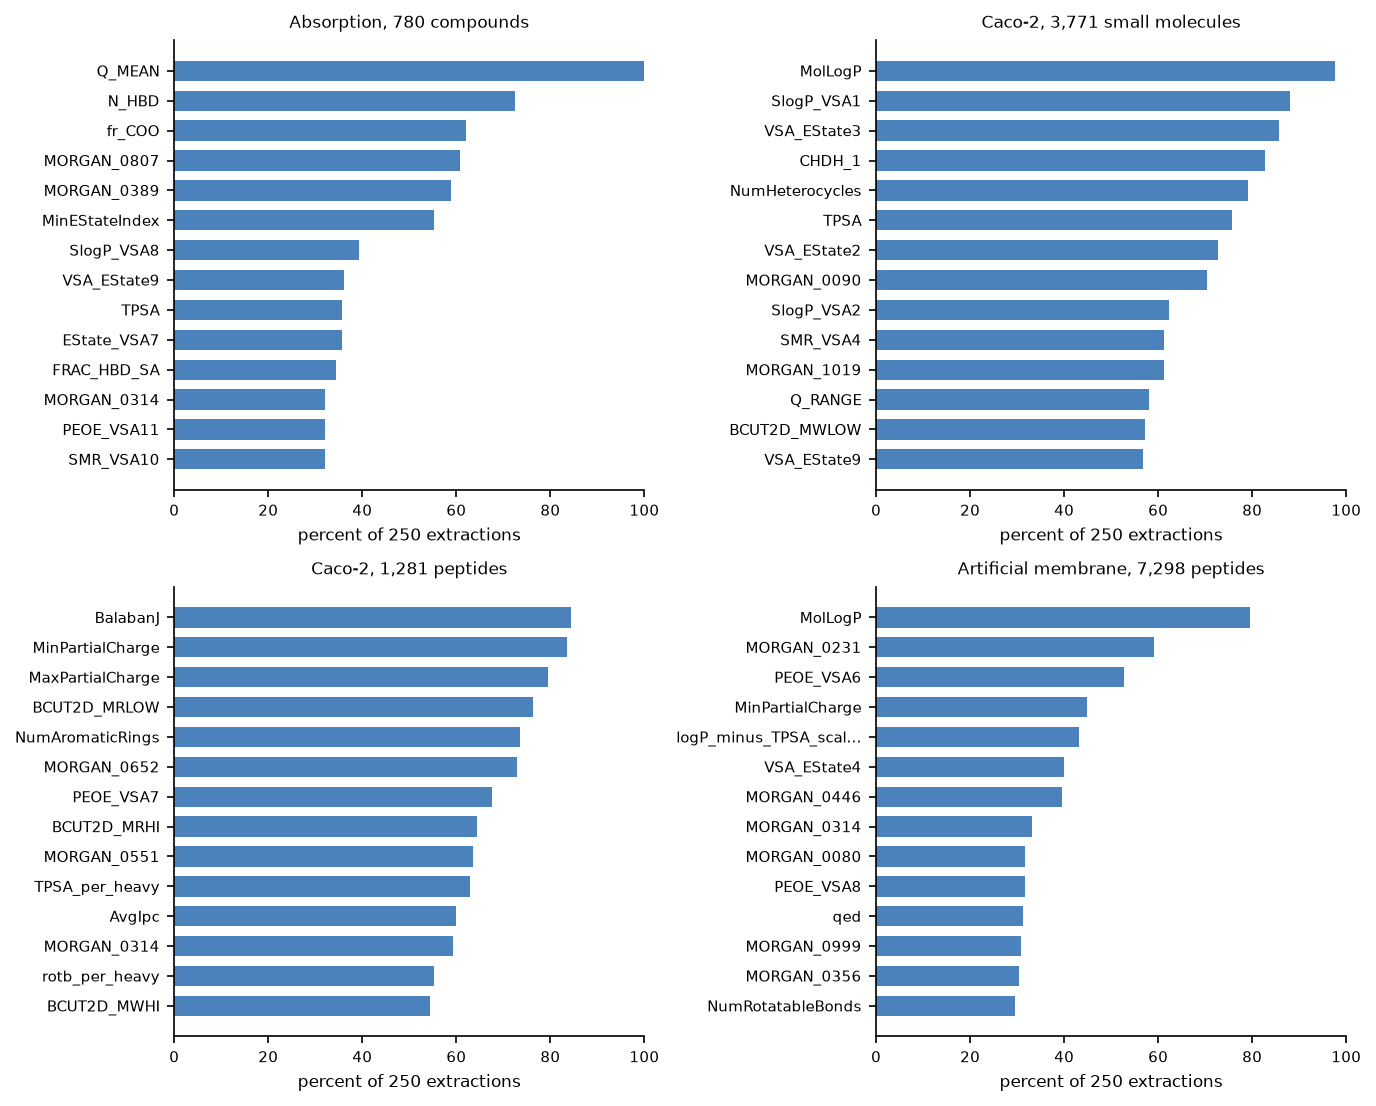
The deployed absorption model reads 25 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
These descriptors are what the absorption model reads. Absorption is led by charge and hydrogen bond donation: the mean partial charge was chosen in every single extraction, and carboxylate count, donor count and donor surface fraction follow it.
| Descriptor | Chosen in |
|---|---|
charge:Q_MEAN | 100.00 percent |
cpsa:N_HBD | 72.40 percent |
rdkit2d:fr_COO | 62.00 percent |
morgan:MORGAN_0807 | 60.80 percent |
morgan:MORGAN_0389 | 58.80 percent |
rdkit2d:MinEStateIndex | 55.20 percent |
rdkit2d:SlogP_VSA8 | 39.20 percent |
rdkit2d:VSA_EState9 | 36.00 percent |
rdkit2d:TPSA | 35.60 percent |
rdkit2d:EState_VSA7 | 35.60 percent |
cpsa:FRAC_HBD_SA | 34.40 percent |
morgan:MORGAN_0314 | 32.00 percent |
rdkit2d:PEOE_VSA11 | 32.00 percent |
rdkit2d:SMR_VSA10 | 32.00 percent |
rdkit2d:PEOE_VSA6 | 31.60 percent |
rdkit2d:fr_bicyclic | 31.20 percent |
rdkit2d:EState_VSA8 | 30.80 percent |
rdkit2d:VSA_EState3 | 30.80 percent |
charge:Q_VAR | 29.60 percent |
morgan:MORGAN_0893 | 29.20 percent |
orig6:SAAA_2 | outside the twenty most chosen |
rdkit2d:VSA_EState8 | outside the twenty most chosen |
rdkit2d:VSA_EState1 | outside the twenty most chosen |
rdkit2d:PEOE_VSA13 | outside the twenty most chosen |
kfm14:NumRotatableBonds | outside the twenty most chosen |
The kfm14 prefix names a block of fourteen size and composition terms: molecular weight, heavy atom and bond counts, rotatable bonds, ring count and element counts. They are borrowed from the ligand featurization of a kinase foundation model, and every one of them is a count or a sum computed directly from the structure.
The 1998 model, searching an unrelated pool with software that no longer runs, chose hydrogen bonding and geometric descriptors. The modern search, over a pool assembled from a different toolkit, arrived at the same physics by a different route.
4. The ceiling is in the data
Published absorption values for the same drug disagree with each other, and the disagreement is not small. Of the 780 compounds modeled, 262 carry more than one published value. Sixty one of those disagree by more than 20 points. Thirty one disagree by more than 40.
Methotrexate appears in the literature at 20, 59, 65, 70 and 100.
A model fitted to labels that disagree by 40 points cannot be more precise than 40 points on those compounds, whatever it does internally. The error below is therefore close to the resolution the published record currently supports, rather than a shortfall against some cleaner achievable number. Reporting a tighter interval would mean reporting a precision the measurements do not have.
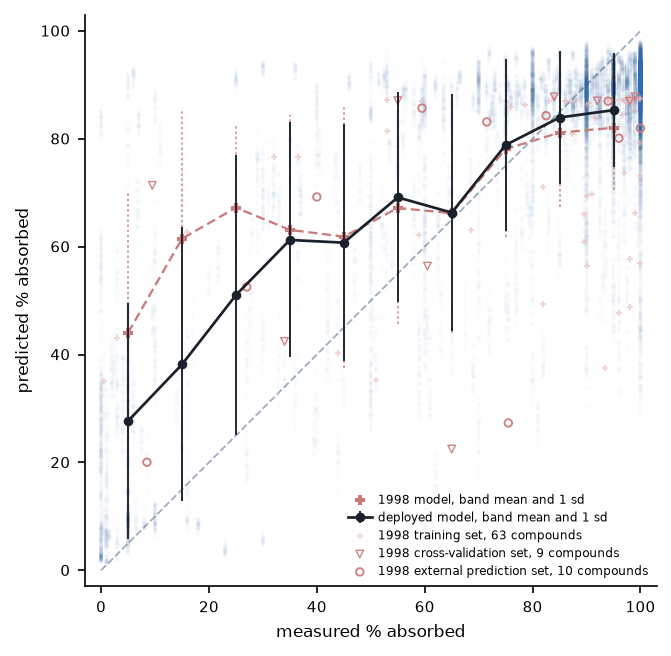
Fitted on all 780 compounds, with 25 descriptors. Nothing is withheld from the shipped model, so none of the numbers below comes from its own fit: they are measured over 250 extractions of the same fixed descriptor set.
| Over 250 extractions of the shipped descriptor set | Value |
|---|---|
| Root mean square error | 20.47 plus or minus 1.71 percentage points |
| Mean absolute error | 14.79 plus or minus 1.11 |
| Correlation | 0.76 plus or minus 0.05 |
| Median absolute error | 10.08 |
| 90th percentile of absolute error | 34.06 |
| Within 11 points | 53.74 percent |
| Within 20 points | 75.39 percent |
| Absorbed or not, at the 30.00 percent threshold | 92.64 percent correct |
Error depends on where the compound sits, so a single overall figure would flatter the hard cases. The bands are below.
| By measured percent absorbed | Root mean square error | Mean absolute error | Predictions |
|---|---|---|---|
| Below 30 percent | 33.61 | 25.72 | 4,000 |
| 30 to 80 percent | 23.95 | 20.19 | 5,949 |
| 80 percent and above | 15.11 | 10.86 | 19,301 |
5. Applicability
The model fails on molecules unlike its training set, and the important part is that it fails quietly. A compound can break no descriptor range and still sit where these descriptors do not resolve it, so the failure looks like an ordinary answer.
So every prediction carries a distance to its five nearest training compounds in the scaled descriptor space, and that distance is compared against the distribution of the same quantity inside the training set. Above the 95th percentile the region is called sparse. Above the 99th it is called far. A prediction from either region is flagged in a visible box above the result rather than in a footnote under it. The prediction is still shown, because hiding an answer teaches a reader nothing, and a flag is itself an answer: it says the model has nothing reliable to offer for this structure.
6. The peptides
The two cyclic peptide models were built the same way, from a peptide pool of 1,257 descriptors: Morgan bits, two-dimensional RDKit descriptors and a peptide-specific block. For the Caco-2 peptides the search chose Balaban's J, a topological index, in 84.40 percent of extractions, the minimum partial charge in 83.60 percent and the maximum in 79.60 percent. For the artificial-membrane peptides it chose calculated logP in 79.60 percent, that same balance term in 43.20 percent, and the fraction of N-methylated amides in 23.20 percent.
Two assays, two models, never pooled. Both are served here and each answers for itself. The membrane model is passive diffusion through lipid, with no cells present. The Caco-2 model is transport across a living monolayer of a human intestinal cell line, where transporters and efflux are active. On the 229 peptides a single study measured in both, the assays correlate 0.62, with the membrane value about half a log unit below the Caco-2 value. A relationship that loose between two assays on the same peptides is the reason this site keeps two models rather than one.
The two released files share 588 peptides, and comparing those two files row by row is the wrong comparison: most of those pairs come from different studies, and across studies the two assays carry no usable relationship. The figures above come from the single-study records instead.
A value of exactly -10.00 is a below-detection placeholder, not a measurement. It stands for a peptide whose permeability was under the limit of the assay, and it appears for 21 peptides in the Caco-2 file and 269 in the membrane file. Treat it as a floor, and censor or filter it before fitting anything to these files.
No combined number is offered, no conversion between them is valid, and a query is never answered by whichever model happens to be available. Falling back would return a confident number measuring something you did not ask about.
A structure is scored by both models in one request, and each result is labeled with the assay it belongs to. Two answers that differ are two measurements that differ, not a disagreement to resolve.
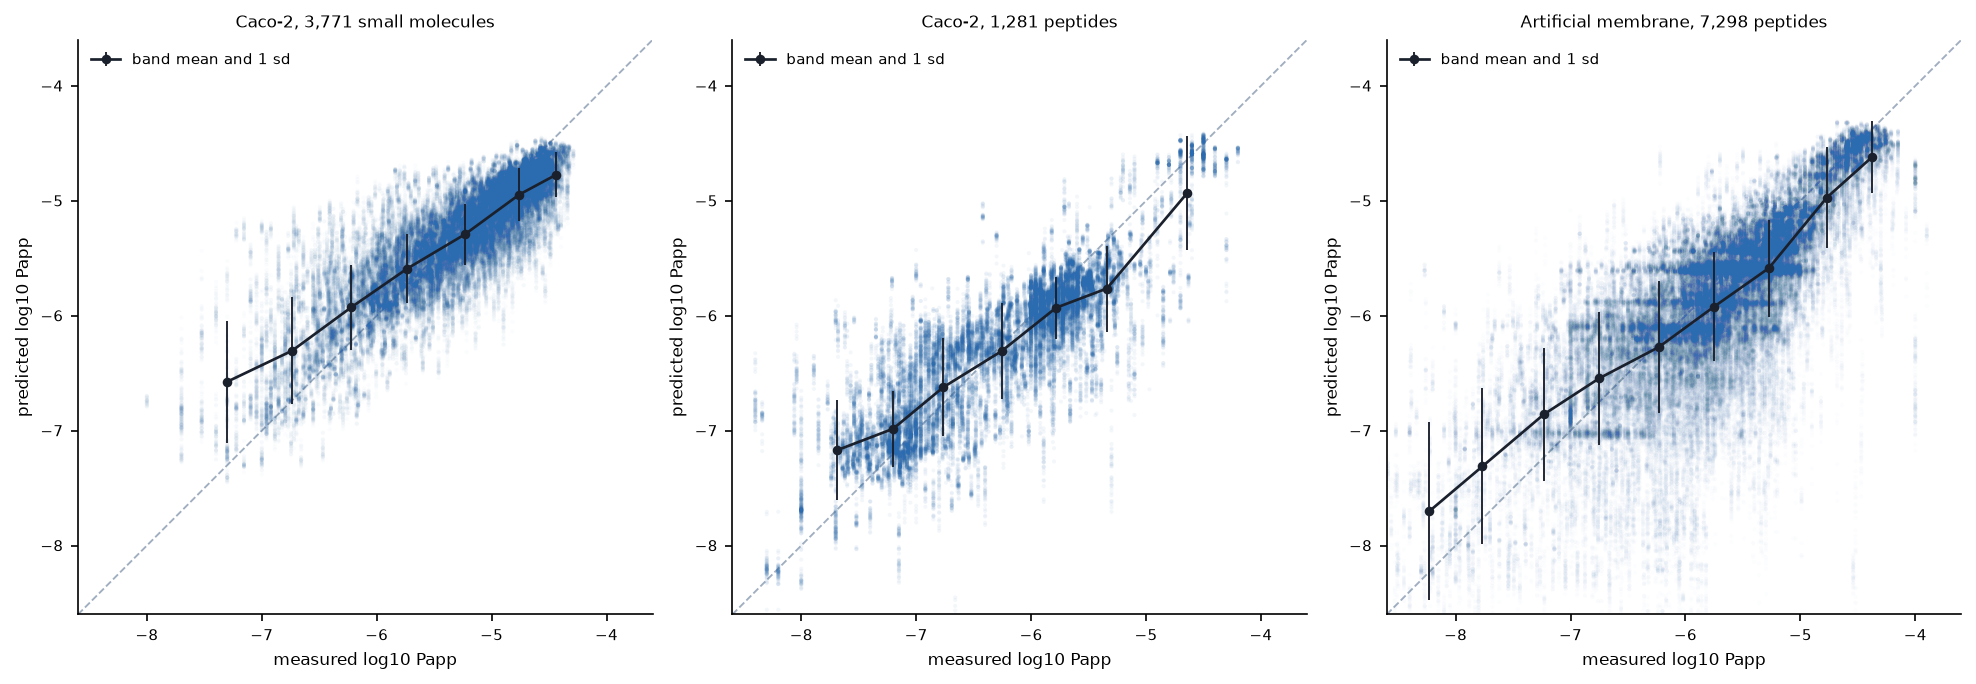
The two Caco-2 panels of that figure, left and middle, are the two models below: the same measurement on different chemistry.
Two Caco-2 models. Pick by chemistry, not by number.
Both predict apparent permeability apical to basolateral across a Caco-2 monolayer, both report log10 Papp with Papp in cm/s. They differ in the chemistry they were fitted on, and they do not substitute for one another.
| Small molecules | Cyclic peptides | |
|---|---|---|
| Compounds | 3,771 | 1,281 |
| Descriptors | 55 | 50 |
| rms | 0.35 | 0.49 |
| R | 0.84 | 0.84 |
| Median error | 0.19 | 0.24 |
| Within 0.30 log units | 68.21 percent | 59.55 percent |
| Within 0.60 log units | 91.55 percent | 85.58 percent |
| Correct side of -6.00 | 90.87 percent | 84.54 percent |
| Equivalent fold error | 2.25 | 3.10 |
| Applicability threshold | 0.84 | 1.10 |
| Source | OpenADMET-ExpansionRx | CycPeptMPDB |
The peptide model scored on the 3,771 small molecules reaches R 0.06, and its own applicability domain places only 5.17 percent of them inside the region it was fitted in. The two are not interchangeable.
The lower error on the small molecules is not a better model. Those compounds are a narrower, denser set; both models reach the same correlation. Each reports whether a query falls inside the region it was fitted in, and that flag travels with every answer.
6b. What the cyclic peptide Caco-2 model achieves and reads
Fitted on all 1,281 peptides, with 50 descriptors, measured over 250 extractions of the fixed consensus set.
| Over 250 extractions of the shipped descriptor set | Value |
|---|---|
| Root mean square error | 0.49 plus or minus 0.04 log units |
| Mean absolute error | 0.34 plus or minus 0.02 |
| Correlation | 0.84 plus or minus 0.03 |
| Median absolute error | 0.24 |
| 90th percentile of absolute error | 0.72 |
| Within 0.30 log units | 59.55 percent |
| Within 0.60 log units | 85.58 percent |
An error of 0.49 log units is a factor of 3.10 in the permeability rate. A prediction of one rate could reasonably be that rate multiplied or divided by about 3.10.
The deployed Caco-2 peptide model reads 50 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
It reads twice as many as the membrane model. The Caco-2 peptide search was run on a grid of 5 to 60 descriptors and settled at a median of 50. Its inputs are not those of the membrane model and the two are not interchangeable.
| Descriptor | Chosen in |
|---|---|
rdkit2d:BalabanJ | 84.40 percent |
rdkit2d:MinPartialCharge | 83.60 percent |
rdkit2d:MaxPartialCharge | 79.60 percent |
rdkit2d:BCUT2D_MRLOW | 76.40 percent |
rdkit2d:NumAromaticRings | 73.60 percent |
morgan:MORGAN_0652 | 72.80 percent |
rdkit2d:PEOE_VSA7 | 67.60 percent |
rdkit2d:BCUT2D_MRHI | 64.40 percent |
morgan:MORGAN_0551 | 63.60 percent |
peptide:TPSA_per_heavy | 62.80 percent |
rdkit2d:AvgIpc | 60.00 percent |
morgan:MORGAN_0314 | 59.20 percent |
peptide:rotb_per_heavy | 55.20 percent |
rdkit2d:BCUT2D_MWHI | 54.40 percent |
peptide:logP_minus_TPSA_scaled | 53.60 percent |
rdkit2d:VSA_EState1 | 48.80 percent |
morgan:MORGAN_0963 | 48.00 percent |
morgan:MORGAN_0685 | 46.80 percent |
morgan:MORGAN_0521 | 46.40 percent |
morgan:MORGAN_0456 | 45.20 percent |
morgan:MORGAN_0759 | outside the twenty most chosen |
morgan:MORGAN_0269 | outside the twenty most chosen |
rdkit2d:VSA_EState3 | outside the twenty most chosen |
rdkit2d:MolLogP | outside the twenty most chosen |
morgan:MORGAN_0084 | outside the twenty most chosen |
morgan:MORGAN_0984 | outside the twenty most chosen |
morgan:MORGAN_0638 | outside the twenty most chosen |
morgan:MORGAN_0285 | outside the twenty most chosen |
rdkit2d:fr_Al_OH | outside the twenty most chosen |
morgan:MORGAN_0914 | outside the twenty most chosen |
morgan:MORGAN_0832 | outside the twenty most chosen |
morgan:MORGAN_0246 | outside the twenty most chosen |
morgan:MORGAN_0523 | outside the twenty most chosen |
morgan:MORGAN_0922 | outside the twenty most chosen |
peptide:n_HBD | outside the twenty most chosen |
morgan:MORGAN_0520 | outside the twenty most chosen |
morgan:MORGAN_0545 | outside the twenty most chosen |
morgan:MORGAN_0811 | outside the twenty most chosen |
morgan:MORGAN_0065 | outside the twenty most chosen |
morgan:MORGAN_0282 | outside the twenty most chosen |
morgan:MORGAN_0730 | outside the twenty most chosen |
morgan:MORGAN_0227 | outside the twenty most chosen |
morgan:MORGAN_0250 | outside the twenty most chosen |
rdkit2d:RingCount | outside the twenty most chosen |
morgan:MORGAN_0288 | outside the twenty most chosen |
morgan:MORGAN_0198 | outside the twenty most chosen |
rdkit2d:fr_piperdine | outside the twenty most chosen |
morgan:MORGAN_0572 | outside the twenty most chosen |
morgan:MORGAN_0080 | outside the twenty most chosen |
morgan:MORGAN_0852 | outside the twenty most chosen |
6c. What the artificial membrane model achieves and reads
Fitted on all 7,298 peptides, with 25 descriptors, measured over 250 extractions of the fixed consensus set.
| Over 250 extractions of the shipped descriptor set | Value |
|---|---|
| Root mean square error | 0.82 plus or minus 0.03 log units |
| Mean absolute error | 0.49 plus or minus 0.02 |
| Correlation | 0.67 plus or minus 0.02 |
| Median absolute error | 0.29 |
| 90th percentile of absolute error | 1.02 |
| Within 0.30 log units | 50.72 percent |
| Within 0.60 log units | 75.99 percent |
An error of 0.82 log units is a factor of 6.68 in the permeability rate. A prediction of one rate could reasonably be that rate multiplied or divided by about 6.68.
The deployed membrane model reads 25 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
These descriptors are what the membrane model reads. Passive permeability is led by size, shape, partial charge and lipophilicity, with polarity entering only per heavy atom. It reads a different set from the absorption model: these are different models of different physics and their inputs are not interchangeable.
| Descriptor | Chosen in |
|---|---|
rdkit2d:MolLogP | 79.60 percent |
morgan:MORGAN_0231 | 59.20 percent |
rdkit2d:PEOE_VSA6 | 52.80 percent |
rdkit2d:MinPartialCharge | 44.80 percent |
peptide:logP_minus_TPSA_scaled | 43.20 percent |
rdkit2d:VSA_EState4 | 40.00 percent |
morgan:MORGAN_0446 | 39.60 percent |
morgan:MORGAN_0314 | 33.20 percent |
morgan:MORGAN_0080 | 31.60 percent |
rdkit2d:PEOE_VSA8 | 31.60 percent |
rdkit2d:qed | 31.20 percent |
morgan:MORGAN_0999 | 30.80 percent |
morgan:MORGAN_0356 | 30.40 percent |
rdkit2d:NumRotatableBonds | 29.60 percent |
peptide:macrocycle_atoms | 29.20 percent |
morgan:MORGAN_0650 | 28.80 percent |
morgan:MORGAN_0340 | 28.40 percent |
morgan:MORGAN_0726 | 26.80 percent |
morgan:MORGAN_0807 | 26.80 percent |
rdkit2d:fr_bicyclic | 26.40 percent |
morgan:MORGAN_0094 | outside the twenty most chosen |
morgan:MORGAN_0435 | outside the twenty most chosen |
rdkit2d:NumAliphaticHeterocycles | outside the twenty most chosen |
rdkit2d:fr_ether | outside the twenty most chosen |
rdkit2d:EState_VSA9 | outside the twenty most chosen |
6d. What the small molecule Caco-2 model achieves and reads
The same procedure, applied to a fourth dataset: apparent permeability across a Caco-2 monolayer measured on small molecules from lead optimization, rather than on cyclic peptides. It predicts the same quantity in the same units as the peptide Caco-2 model, and the two are not interchangeable.
Fitted on all 3,771 small molecules, with 55 descriptors, measured over 250 extractions of the fixed consensus set.
| Over 250 extractions of the shipped descriptor set | Value |
|---|---|
| Root mean square error | 0.35 plus or minus 0.01 log units |
| Mean absolute error | 0.26 plus or minus 0.01 |
| Correlation | 0.84 plus or minus 0.01 |
| Median absolute error | 0.19 |
| 90th percentile of absolute error | 0.56 |
| Within 0.30 log units | 68.21 percent |
| Within 0.60 log units | 91.55 percent |
An error of 0.35 log units is a factor of 2.25 in the permeability rate. A prediction of one rate could reasonably be that rate multiplied or divided by about 2.25.
The deployed small-molecule Caco-2 model reads 55 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
| Descriptor | Chosen in |
|---|---|
rdkit2d:MolLogP | 97.60 percent |
rdkit2d:SlogP_VSA1 | 88.00 percent |
rdkit2d:VSA_EState3 | 85.60 percent |
orig6:CHDH_1 | 82.80 percent |
rdkit2d:NumHeterocycles | 79.20 percent |
rdkit2d:TPSA | 75.60 percent |
rdkit2d:VSA_EState2 | 72.80 percent |
morgan:MORGAN_0090 | 70.40 percent |
rdkit2d:SlogP_VSA2 | 62.40 percent |
rdkit2d:SMR_VSA4 | 61.20 percent |
morgan:MORGAN_1019 | 61.20 percent |
charge:Q_RANGE | 58.00 percent |
rdkit2d:BCUT2D_MWLOW | 57.20 percent |
rdkit2d:VSA_EState9 | 56.80 percent |
rdkit2d:SMR_VSA9 | 56.00 percent |
charge:Q_MAX | 53.60 percent |
rdkit2d:NumAromaticHeterocycles | 53.20 percent |
rdkit2d:VSA_EState5 | 52.80 percent |
kfm14:count_N | 52.00 percent |
rdkit2d:PEOE_VSA1 | 49.60 percent |
rdkit2d:SlogP_VSA8 | outside the twenty most chosen |
rdkit2d:fr_pyridine | outside the twenty most chosen |
cpsa:N_HBD | outside the twenty most chosen |
morgan:MORGAN_0625 | outside the twenty most chosen |
morgan:MORGAN_0506 | outside the twenty most chosen |
rdkit2d:fr_NH1 | outside the twenty most chosen |
rdkit2d:fr_Ndealkylation2 | outside the twenty most chosen |
morgan:MORGAN_0562 | outside the twenty most chosen |
rdkit2d:PEOE_VSA11 | outside the twenty most chosen |
rdkit2d:PEOE_VSA10 | outside the twenty most chosen |
rdkit2d:NumAliphaticHeterocycles | outside the twenty most chosen |
charge:Q_MIN | outside the twenty most chosen |
morgan:MORGAN_0726 | outside the twenty most chosen |
kfm14:RingCount | outside the twenty most chosen |
rdkit2d:SlogP_VSA10 | outside the twenty most chosen |
rdkit2d:SlogP_VSA4 | outside the twenty most chosen |
morgan:MORGAN_0333 | outside the twenty most chosen |
rdkit2d:SMR_VSA7 | outside the twenty most chosen |
rdkit2d:HallKierAlpha | outside the twenty most chosen |
rdkit2d:PEOE_VSA2 | outside the twenty most chosen |
rdkit2d:NumAromaticCarbocycles | outside the twenty most chosen |
rdkit2d:PEOE_VSA6 | outside the twenty most chosen |
cpsa:RNCG | outside the twenty most chosen |
rdkit2d:BCUT2D_MWHI | outside the twenty most chosen |
morgan:MORGAN_0004 | outside the twenty most chosen |
rdkit2d:SMR_VSA10 | outside the twenty most chosen |
rdkit2d:qed | outside the twenty most chosen |
morgan:MORGAN_0223 | outside the twenty most chosen |
rdkit2d:VSA_EState6 | outside the twenty most chosen |
morgan:MORGAN_0352 | outside the twenty most chosen |
morgan:MORGAN_0207 | outside the twenty most chosen |
morgan:MORGAN_0456 | outside the twenty most chosen |
cpsa:WNSA_1 | outside the twenty most chosen |
rdkit2d:SMR_VSA6 | outside the twenty most chosen |
morgan:MORGAN_0721 | outside the twenty most chosen |
The kfm14 prefix names a block of fourteen size and composition terms: molecular weight, heavy atom and bond counts, rotatable bonds, ring count and element counts. They are borrowed from the ligand featurization of a kinase foundation model, and every one of them is a count or a sum computed directly from the structure.
What the numbers are
| Quantity | Value |
|---|---|
| Absorption, compounds fitted | 780 |
| Absorption, descriptors | 25 |
| Absorption, root mean square error, percentage points | 20.47 plus or minus 1.71 |
| Absorption, correlation | 0.76 plus or minus 0.05 |
| Absorption, decision accuracy at 30.00 | 92.64 percent |
| Caco-2 small molecules, compounds fitted | 3,771 |
| Caco-2 small molecules, descriptors | 55 |
| Caco-2 small molecules, root mean square error, log units | 0.35 plus or minus 0.01 |
| Caco-2 small molecules, correlation | 0.84 plus or minus 0.01 |
| Caco-2 small molecules, decision accuracy at -6.00 | 90.87 percent |
| Caco-2 peptides, compounds fitted | 1,281 |
| Caco-2 peptides, descriptors | 50 |
| Caco-2 peptides, root mean square error, log units | 0.49 plus or minus 0.04 |
| Caco-2 peptides, correlation | 0.84 plus or minus 0.03 |
| Caco-2 peptides, decision accuracy at -6.00 | 84.54 percent |
| Artificial-membrane peptides, compounds fitted | 7,298 |
| Artificial-membrane peptides, descriptors | 25 |
| Artificial-membrane peptides, root mean square error, log units | 0.82 plus or minus 0.03 |
| Artificial-membrane peptides, correlation | 0.67 plus or minus 0.02 |
| Artificial-membrane peptides, decision accuracy at -6.00 | 79.40 percent |
Every figure above is measured over 250 extractions of the descriptor set that ships, not over the search that found it, and not on the shipped model's own training data.
No comparison against a model that answers the training mean appears here or anywhere on this site. Such a reference makes any model look good and tells a reader nothing about whether an answer can be used. What an error means in practice is in the bands and in the decision accuracy.