Data
What each of the four models was actually fitted to, where those measurements came from, and what the algorithm chose from them. Nothing on this site is fitted to anything that is not on this page.
Absorption
The absorption model is fitted to 780 compounds carrying a continuous percent-absorbed label. Every step of the chain is stated: 783 compounds in the compilation, 2 entries for a fluorescent paracellular marker excluded because it is not a drug and its permeation is not a property of an oral dose, and 1 compound whose geometry would not embed, leaving 780. The label is percent of an oral dose absorbed in humans, and it runs from 0 to 100, so the model is a regression and not a two-class call.
The labels come from the human intestinal absorption and bioavailability datasets compiled by the Institute of Biophysics and Biomedical Engineering, Bulgarian Academy of Sciences, for the COSMOS project, described at biomed.bas.bg/qsarmm/Human_intestinal_absorption_and_bioavalability. They are published measurements, which means they carry the literature's disagreements with them. Of the 780 compounds modeled, 262 carry more than one published value; 61 of those disagree by more than 20 points and 31 by more than 40. Methotrexate appears at 20, 59, 65, 70 and 100. Where a compound carries several values, the median is used, and the spread is not discarded: it is what sets the ceiling described on How it works.
| Quantity | Value |
|---|---|
| Absorption, compounds fitted | 780 |
| Absorption, descriptors | 25 |
| Absorption, root mean square error, percentage points | 20.47 plus or minus 1.71 |
| Absorption, correlation | 0.76 plus or minus 0.05 |
| Absorption, decision accuracy at 30.00 | 92.64 percent |
| Caco-2 small molecules, compounds fitted | 3,771 |
| Caco-2 small molecules, descriptors | 55 |
| Caco-2 small molecules, root mean square error, log units | 0.35 plus or minus 0.01 |
| Caco-2 small molecules, correlation | 0.84 plus or minus 0.01 |
| Caco-2 small molecules, decision accuracy at -6.00 | 90.87 percent |
| Caco-2 peptides, compounds fitted | 1,281 |
| Caco-2 peptides, descriptors | 50 |
| Caco-2 peptides, root mean square error, log units | 0.49 plus or minus 0.04 |
| Caco-2 peptides, correlation | 0.84 plus or minus 0.03 |
| Caco-2 peptides, decision accuracy at -6.00 | 84.54 percent |
| Artificial-membrane peptides, compounds fitted | 7,298 |
| Artificial-membrane peptides, descriptors | 25 |
| Artificial-membrane peptides, root mean square error, log units | 0.82 plus or minus 0.03 |
| Artificial-membrane peptides, correlation | 0.67 plus or minus 0.02 |
| Artificial-membrane peptides, decision accuracy at -6.00 | 79.40 percent |
Every figure above is measured over 250 extractions of the descriptor set that ships, not over the search that found it, and not on the shipped model's own training data.
No comparison against a model that answers the training mean appears here or anywhere on this site. Such a reference makes any model look good and tells a reader nothing about whether an answer can be used. What an error means in practice is in the bands and in the decision accuracy.
Peptides
The peptide measurements come from CycPeptMPDB, the public database of cyclic peptide membrane permeability. They are split into two datasets by what was measured.
The Caco-2 dataset holds 1,281 cyclic peptides measured on a monolayer of a human intestinal cell line. The artificial-membrane dataset holds 7,298 cyclic peptides measured on artificial membranes of the PAMPA class. Both report a log10 apparent permeability, and that shared unit is exactly what makes pooling them tempting and wrong.
These are different assays on different populations. A cell monolayer has transporters, efflux and metabolism in it; an artificial membrane has none of those. The two populations are also not the same peptides: one dataset is roughly six times the size of the other and reaches further into macrocyclic chemistry. Where a single study measured both, the two assays are related loosely enough that neither stands in for the other, as the figures below set out.
So there are two peptide models, both served, reported side by side, and no number on this site is ever computed from both. There is no conversion between them because none is supported by this data.
Two assays, two models, never pooled. Both are served here and each answers for itself. The membrane model is passive diffusion through lipid, with no cells present. The Caco-2 model is transport across a living monolayer of a human intestinal cell line, where transporters and efflux are active. On the 229 peptides a single study measured in both, the assays correlate 0.62, with the membrane value about half a log unit below the Caco-2 value. A relationship that loose between two assays on the same peptides is the reason this site keeps two models rather than one.
The two released files share 588 peptides, and comparing those two files row by row is the wrong comparison: most of those pairs come from different studies, and across studies the two assays carry no usable relationship. The figures above come from the single-study records instead.
A value of exactly -10.00 is a below-detection placeholder, not a measurement. It stands for a peptide whose permeability was under the limit of the assay, and it appears for 21 peptides in the Caco-2 file and 269 in the membrane file. Treat it as a floor, and censor or filter it before fitting anything to these files.
No combined number is offered, no conversion between them is valid, and a query is never answered by whichever model happens to be available. Falling back would return a confident number measuring something you did not ask about.
A structure is scored by both models in one request, and each result is labeled with the assay it belongs to. Two answers that differ are two measurements that differ, not a disagreement to resolve.
Small molecules, Caco-2
The fourth set holds 3,771 small molecules from lead optimization, measured for apparent permeability across a Caco-2 monolayer and reported as log10 Papp with Papp in cm/s. It comes from the OpenADMET-ExpansionRx challenge, contributed by Expansion Therapeutics and released by the OpenADMET consortium under CC-BY-4.0.
Two Caco-2 models. Pick by chemistry, not by number.
Both predict apparent permeability apical to basolateral across a Caco-2 monolayer, both report log10 Papp with Papp in cm/s. They differ in the chemistry they were fitted on, and they do not substitute for one another.
| Small molecules | Cyclic peptides | |
|---|---|---|
| Compounds | 3,771 | 1,281 |
| Descriptors | 55 | 50 |
| rms | 0.35 | 0.49 |
| R | 0.84 | 0.84 |
| Median error | 0.19 | 0.24 |
| Within 0.30 log units | 68.21 percent | 59.55 percent |
| Within 0.60 log units | 91.55 percent | 85.58 percent |
| Correct side of -6.00 | 90.87 percent | 84.54 percent |
| Equivalent fold error | 2.25 | 3.10 |
| Applicability threshold | 0.84 | 1.10 |
| Source | OpenADMET-ExpansionRx | CycPeptMPDB |
The peptide model scored on the 3,771 small molecules reaches R 0.06, and its own applicability domain places only 5.17 percent of them inside the region it was fitted in. The two are not interchangeable.
The lower error on the small molecules is not a better model. Those compounds are a narrower, denser set; both models reach the same correlation. Each reports whether a query falls inside the region it was fitted in, and that flag travels with every answer.
The descriptors each model uses
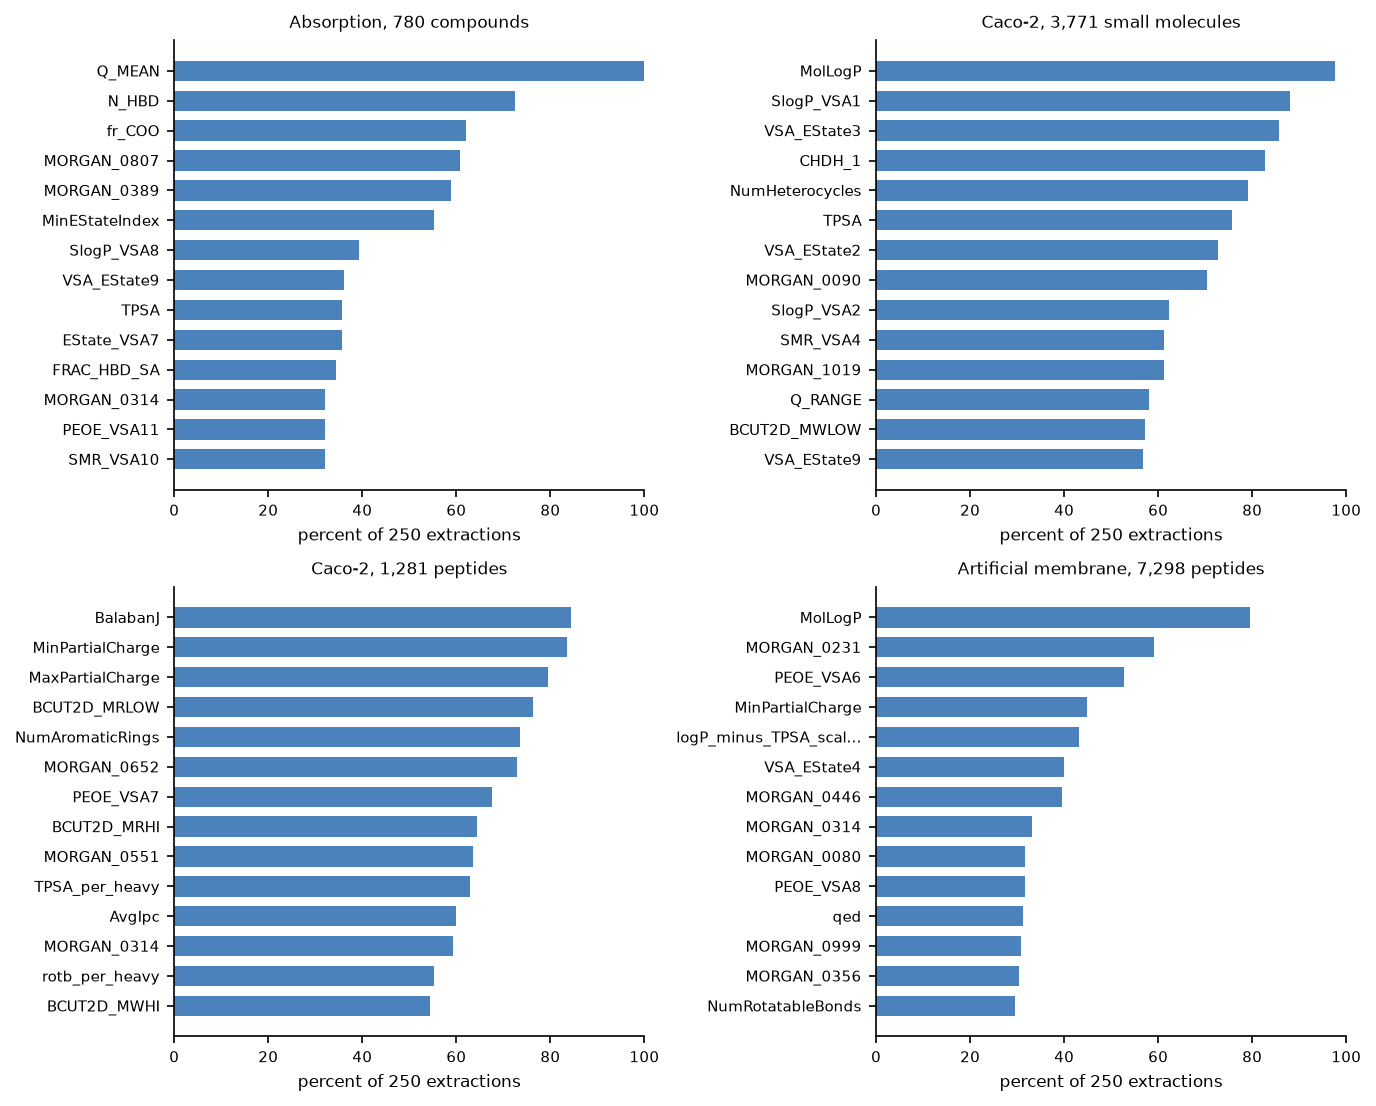
The deployed absorption model reads 25 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
These descriptors are what the absorption model reads. Absorption is led by charge and hydrogen bond donation: the mean partial charge was chosen in every single extraction, and carboxylate count, donor count and donor surface fraction follow it.
| Descriptor | Chosen in |
|---|---|
charge:Q_MEAN | 100.00 percent |
cpsa:N_HBD | 72.40 percent |
rdkit2d:fr_COO | 62.00 percent |
morgan:MORGAN_0807 | 60.80 percent |
morgan:MORGAN_0389 | 58.80 percent |
rdkit2d:MinEStateIndex | 55.20 percent |
rdkit2d:SlogP_VSA8 | 39.20 percent |
rdkit2d:VSA_EState9 | 36.00 percent |
rdkit2d:TPSA | 35.60 percent |
rdkit2d:EState_VSA7 | 35.60 percent |
cpsa:FRAC_HBD_SA | 34.40 percent |
morgan:MORGAN_0314 | 32.00 percent |
rdkit2d:PEOE_VSA11 | 32.00 percent |
rdkit2d:SMR_VSA10 | 32.00 percent |
rdkit2d:PEOE_VSA6 | 31.60 percent |
rdkit2d:fr_bicyclic | 31.20 percent |
rdkit2d:EState_VSA8 | 30.80 percent |
rdkit2d:VSA_EState3 | 30.80 percent |
charge:Q_VAR | 29.60 percent |
morgan:MORGAN_0893 | 29.20 percent |
orig6:SAAA_2 | outside the twenty most chosen |
rdkit2d:VSA_EState8 | outside the twenty most chosen |
rdkit2d:VSA_EState1 | outside the twenty most chosen |
rdkit2d:PEOE_VSA13 | outside the twenty most chosen |
kfm14:NumRotatableBonds | outside the twenty most chosen |
The kfm14 prefix names a block of fourteen size and composition terms: molecular weight, heavy atom and bond counts, rotatable bonds, ring count and element counts. They are borrowed from the ligand featurization of a kinase foundation model, and every one of them is a count or a sum computed directly from the structure.
The deployed Caco-2 peptide model reads 50 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
It reads twice as many as the membrane model. The Caco-2 peptide search was run on a grid of 5 to 60 descriptors and settled at a median of 50. Its inputs are not those of the membrane model and the two are not interchangeable.
| Descriptor | Chosen in |
|---|---|
rdkit2d:BalabanJ | 84.40 percent |
rdkit2d:MinPartialCharge | 83.60 percent |
rdkit2d:MaxPartialCharge | 79.60 percent |
rdkit2d:BCUT2D_MRLOW | 76.40 percent |
rdkit2d:NumAromaticRings | 73.60 percent |
morgan:MORGAN_0652 | 72.80 percent |
rdkit2d:PEOE_VSA7 | 67.60 percent |
rdkit2d:BCUT2D_MRHI | 64.40 percent |
morgan:MORGAN_0551 | 63.60 percent |
peptide:TPSA_per_heavy | 62.80 percent |
rdkit2d:AvgIpc | 60.00 percent |
morgan:MORGAN_0314 | 59.20 percent |
peptide:rotb_per_heavy | 55.20 percent |
rdkit2d:BCUT2D_MWHI | 54.40 percent |
peptide:logP_minus_TPSA_scaled | 53.60 percent |
rdkit2d:VSA_EState1 | 48.80 percent |
morgan:MORGAN_0963 | 48.00 percent |
morgan:MORGAN_0685 | 46.80 percent |
morgan:MORGAN_0521 | 46.40 percent |
morgan:MORGAN_0456 | 45.20 percent |
morgan:MORGAN_0759 | outside the twenty most chosen |
morgan:MORGAN_0269 | outside the twenty most chosen |
rdkit2d:VSA_EState3 | outside the twenty most chosen |
rdkit2d:MolLogP | outside the twenty most chosen |
morgan:MORGAN_0084 | outside the twenty most chosen |
morgan:MORGAN_0984 | outside the twenty most chosen |
morgan:MORGAN_0638 | outside the twenty most chosen |
morgan:MORGAN_0285 | outside the twenty most chosen |
rdkit2d:fr_Al_OH | outside the twenty most chosen |
morgan:MORGAN_0914 | outside the twenty most chosen |
morgan:MORGAN_0832 | outside the twenty most chosen |
morgan:MORGAN_0246 | outside the twenty most chosen |
morgan:MORGAN_0523 | outside the twenty most chosen |
morgan:MORGAN_0922 | outside the twenty most chosen |
peptide:n_HBD | outside the twenty most chosen |
morgan:MORGAN_0520 | outside the twenty most chosen |
morgan:MORGAN_0545 | outside the twenty most chosen |
morgan:MORGAN_0811 | outside the twenty most chosen |
morgan:MORGAN_0065 | outside the twenty most chosen |
morgan:MORGAN_0282 | outside the twenty most chosen |
morgan:MORGAN_0730 | outside the twenty most chosen |
morgan:MORGAN_0227 | outside the twenty most chosen |
morgan:MORGAN_0250 | outside the twenty most chosen |
rdkit2d:RingCount | outside the twenty most chosen |
morgan:MORGAN_0288 | outside the twenty most chosen |
morgan:MORGAN_0198 | outside the twenty most chosen |
rdkit2d:fr_piperdine | outside the twenty most chosen |
morgan:MORGAN_0572 | outside the twenty most chosen |
morgan:MORGAN_0080 | outside the twenty most chosen |
morgan:MORGAN_0852 | outside the twenty most chosen |
The deployed membrane model reads 25 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
These descriptors are what the membrane model reads. Passive permeability is led by size, shape, partial charge and lipophilicity, with polarity entering only per heavy atom. It reads a different set from the absorption model: these are different models of different physics and their inputs are not interchangeable.
| Descriptor | Chosen in |
|---|---|
rdkit2d:MolLogP | 79.60 percent |
morgan:MORGAN_0231 | 59.20 percent |
rdkit2d:PEOE_VSA6 | 52.80 percent |
rdkit2d:MinPartialCharge | 44.80 percent |
peptide:logP_minus_TPSA_scaled | 43.20 percent |
rdkit2d:VSA_EState4 | 40.00 percent |
morgan:MORGAN_0446 | 39.60 percent |
morgan:MORGAN_0314 | 33.20 percent |
morgan:MORGAN_0080 | 31.60 percent |
rdkit2d:PEOE_VSA8 | 31.60 percent |
rdkit2d:qed | 31.20 percent |
morgan:MORGAN_0999 | 30.80 percent |
morgan:MORGAN_0356 | 30.40 percent |
rdkit2d:NumRotatableBonds | 29.60 percent |
peptide:macrocycle_atoms | 29.20 percent |
morgan:MORGAN_0650 | 28.80 percent |
morgan:MORGAN_0340 | 28.40 percent |
morgan:MORGAN_0726 | 26.80 percent |
morgan:MORGAN_0807 | 26.80 percent |
rdkit2d:fr_bicyclic | 26.40 percent |
morgan:MORGAN_0094 | outside the twenty most chosen |
morgan:MORGAN_0435 | outside the twenty most chosen |
rdkit2d:NumAliphaticHeterocycles | outside the twenty most chosen |
rdkit2d:fr_ether | outside the twenty most chosen |
rdkit2d:EState_VSA9 | outside the twenty most chosen |
The deployed small-molecule Caco-2 model reads 55 descriptors. Every one of them is listed below, read from the bundle rather than typed. The recurrence beside each is a property of the search that chose it, not of the model.
| Descriptor | Chosen in |
|---|---|
rdkit2d:MolLogP | 97.60 percent |
rdkit2d:SlogP_VSA1 | 88.00 percent |
rdkit2d:VSA_EState3 | 85.60 percent |
orig6:CHDH_1 | 82.80 percent |
rdkit2d:NumHeterocycles | 79.20 percent |
rdkit2d:TPSA | 75.60 percent |
rdkit2d:VSA_EState2 | 72.80 percent |
morgan:MORGAN_0090 | 70.40 percent |
rdkit2d:SlogP_VSA2 | 62.40 percent |
rdkit2d:SMR_VSA4 | 61.20 percent |
morgan:MORGAN_1019 | 61.20 percent |
charge:Q_RANGE | 58.00 percent |
rdkit2d:BCUT2D_MWLOW | 57.20 percent |
rdkit2d:VSA_EState9 | 56.80 percent |
rdkit2d:SMR_VSA9 | 56.00 percent |
charge:Q_MAX | 53.60 percent |
rdkit2d:NumAromaticHeterocycles | 53.20 percent |
rdkit2d:VSA_EState5 | 52.80 percent |
kfm14:count_N | 52.00 percent |
rdkit2d:PEOE_VSA1 | 49.60 percent |
rdkit2d:SlogP_VSA8 | outside the twenty most chosen |
rdkit2d:fr_pyridine | outside the twenty most chosen |
cpsa:N_HBD | outside the twenty most chosen |
morgan:MORGAN_0625 | outside the twenty most chosen |
morgan:MORGAN_0506 | outside the twenty most chosen |
rdkit2d:fr_NH1 | outside the twenty most chosen |
rdkit2d:fr_Ndealkylation2 | outside the twenty most chosen |
morgan:MORGAN_0562 | outside the twenty most chosen |
rdkit2d:PEOE_VSA11 | outside the twenty most chosen |
rdkit2d:PEOE_VSA10 | outside the twenty most chosen |
rdkit2d:NumAliphaticHeterocycles | outside the twenty most chosen |
charge:Q_MIN | outside the twenty most chosen |
morgan:MORGAN_0726 | outside the twenty most chosen |
kfm14:RingCount | outside the twenty most chosen |
rdkit2d:SlogP_VSA10 | outside the twenty most chosen |
rdkit2d:SlogP_VSA4 | outside the twenty most chosen |
morgan:MORGAN_0333 | outside the twenty most chosen |
rdkit2d:SMR_VSA7 | outside the twenty most chosen |
rdkit2d:HallKierAlpha | outside the twenty most chosen |
rdkit2d:PEOE_VSA2 | outside the twenty most chosen |
rdkit2d:NumAromaticCarbocycles | outside the twenty most chosen |
rdkit2d:PEOE_VSA6 | outside the twenty most chosen |
cpsa:RNCG | outside the twenty most chosen |
rdkit2d:BCUT2D_MWHI | outside the twenty most chosen |
morgan:MORGAN_0004 | outside the twenty most chosen |
rdkit2d:SMR_VSA10 | outside the twenty most chosen |
rdkit2d:qed | outside the twenty most chosen |
morgan:MORGAN_0223 | outside the twenty most chosen |
rdkit2d:VSA_EState6 | outside the twenty most chosen |
morgan:MORGAN_0352 | outside the twenty most chosen |
morgan:MORGAN_0207 | outside the twenty most chosen |
morgan:MORGAN_0456 | outside the twenty most chosen |
cpsa:WNSA_1 | outside the twenty most chosen |
rdkit2d:SMR_VSA6 | outside the twenty most chosen |
morgan:MORGAN_0721 | outside the twenty most chosen |
The kfm14 prefix names a block of fourteen size and composition terms: molecular weight, heavy atom and bond counts, rotatable bonds, ring count and element counts. They are borrowed from the ligand featurization of a kinase foundation model, and every one of them is a count or a sum computed directly from the structure.
Getting the tables
The four training tables and the four fitted models are on Download, with their checksums.